GenAI can have a massive, positive impact on our society and economy – if it is adopted at scale in public and private sector organisations. Using GenAI in such real-world situations, at scale, raises the quality and reliability bar significantly.
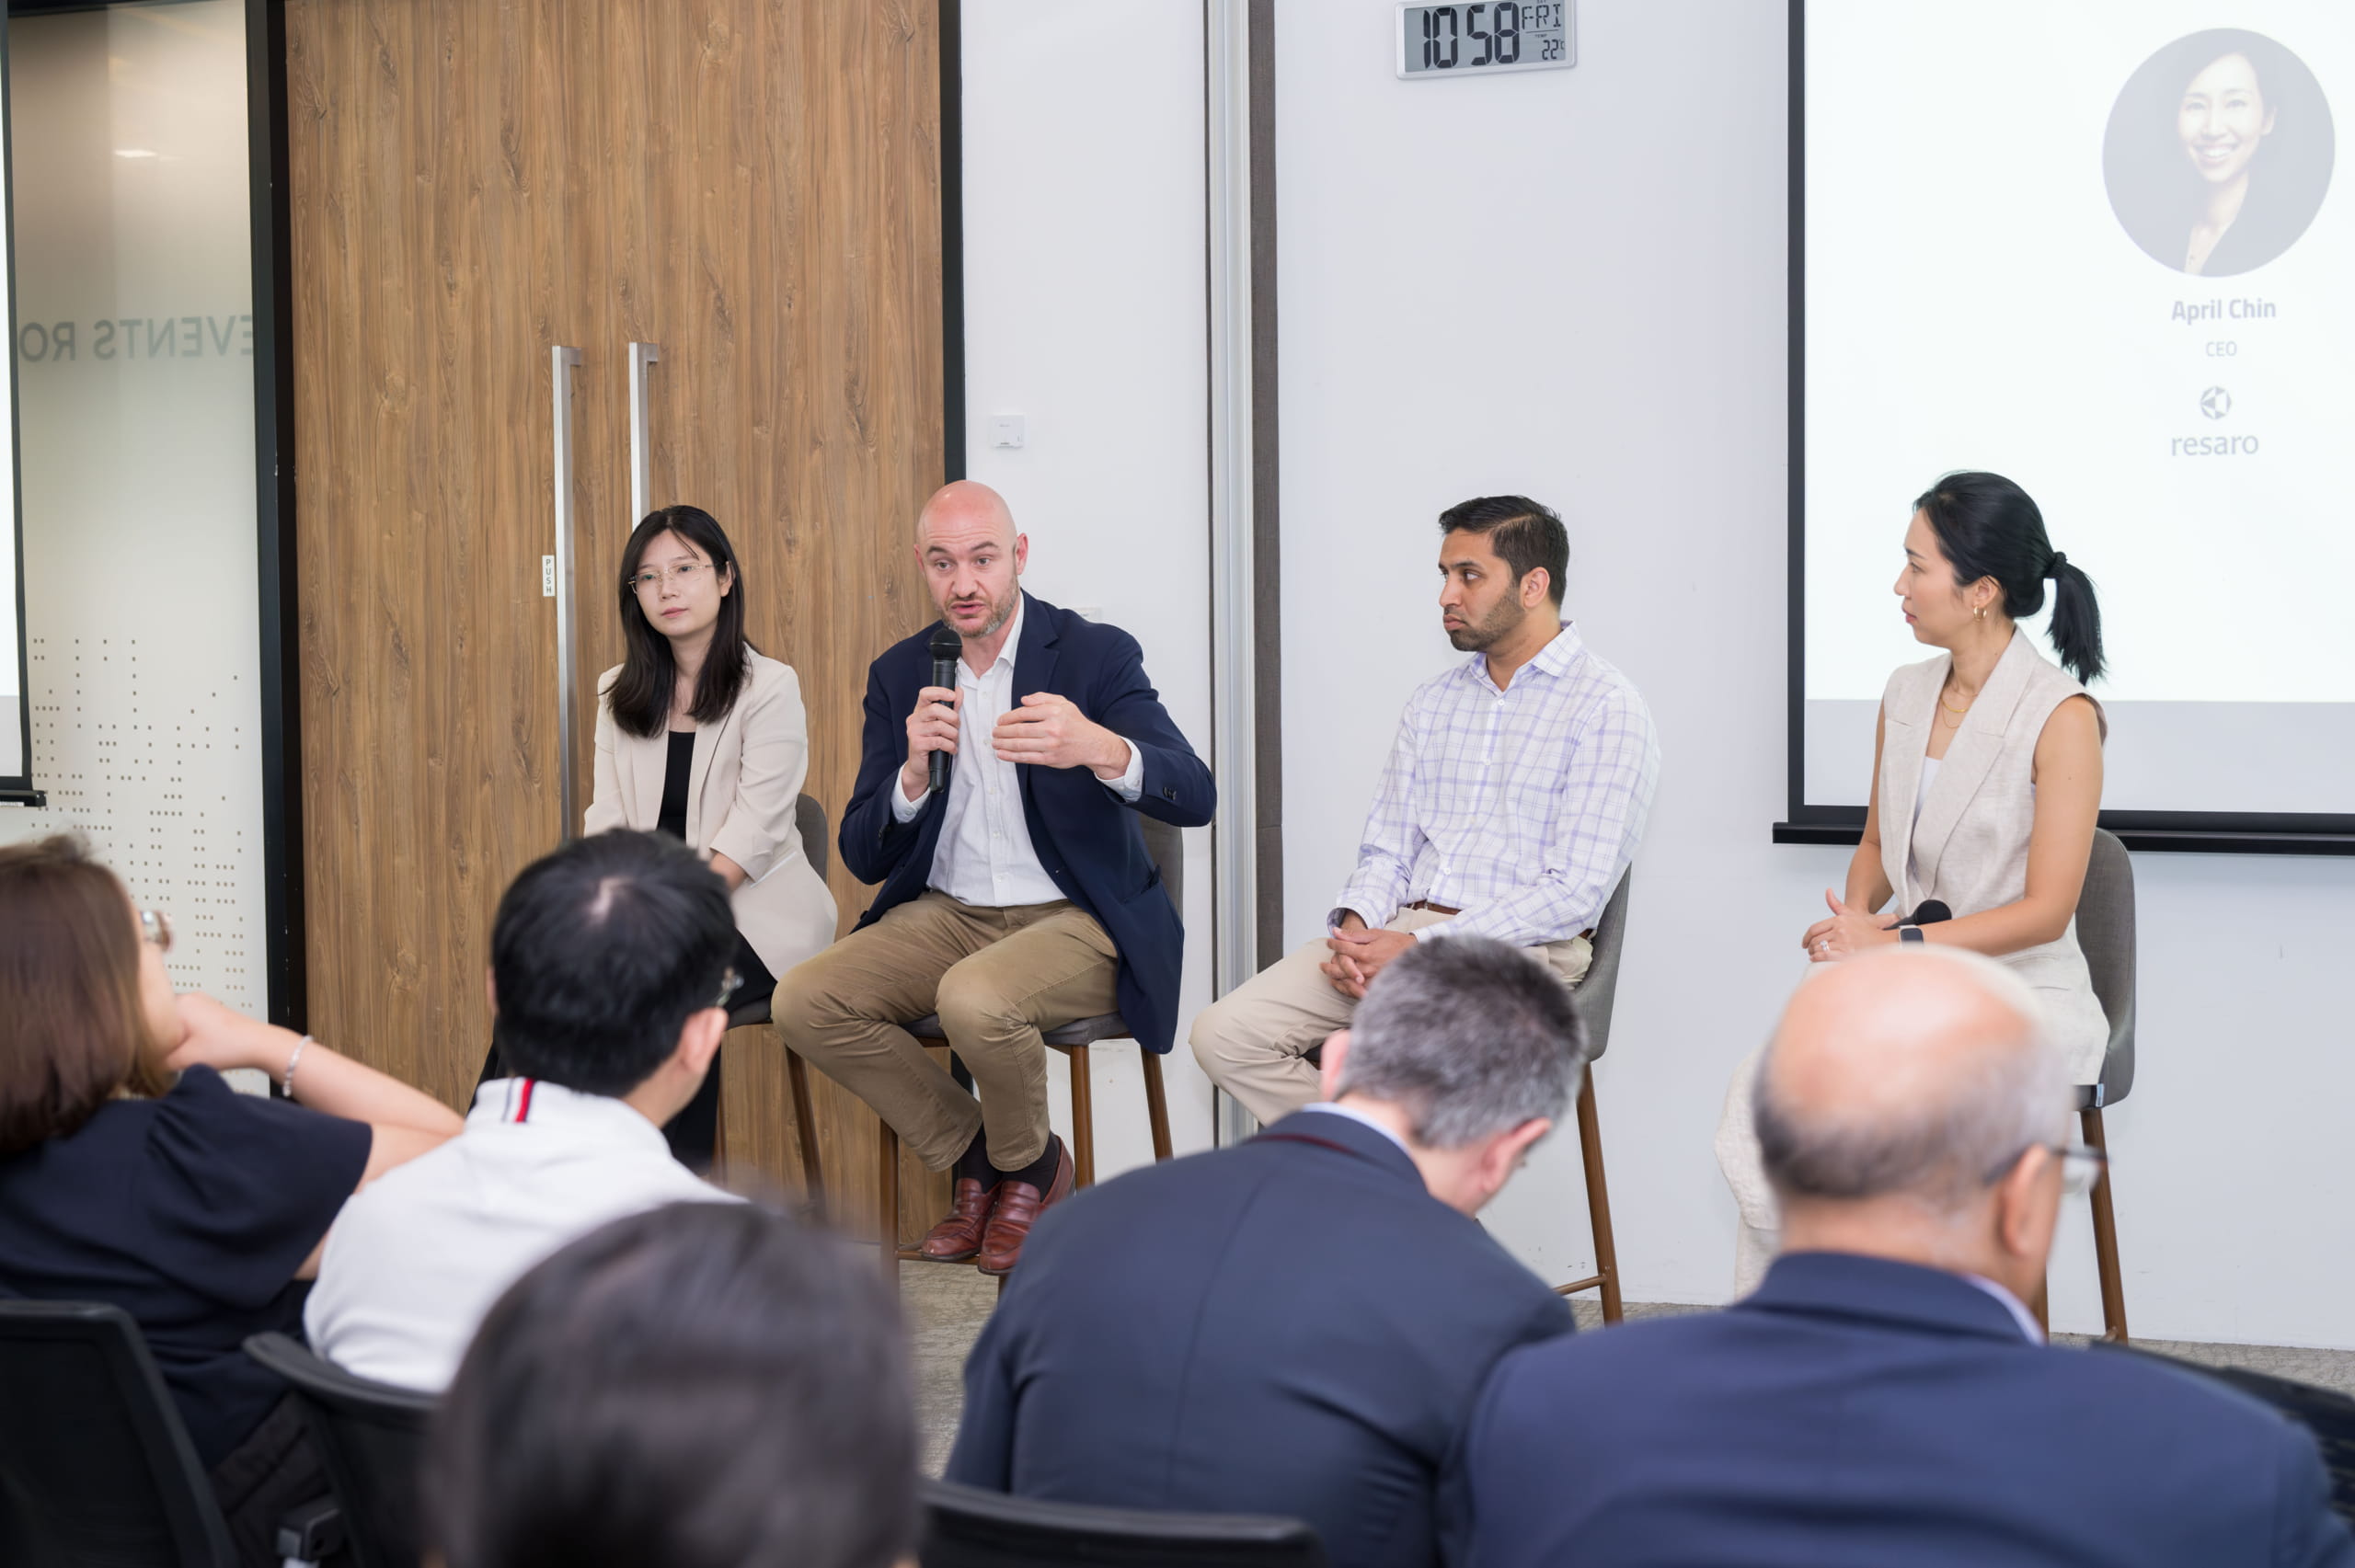
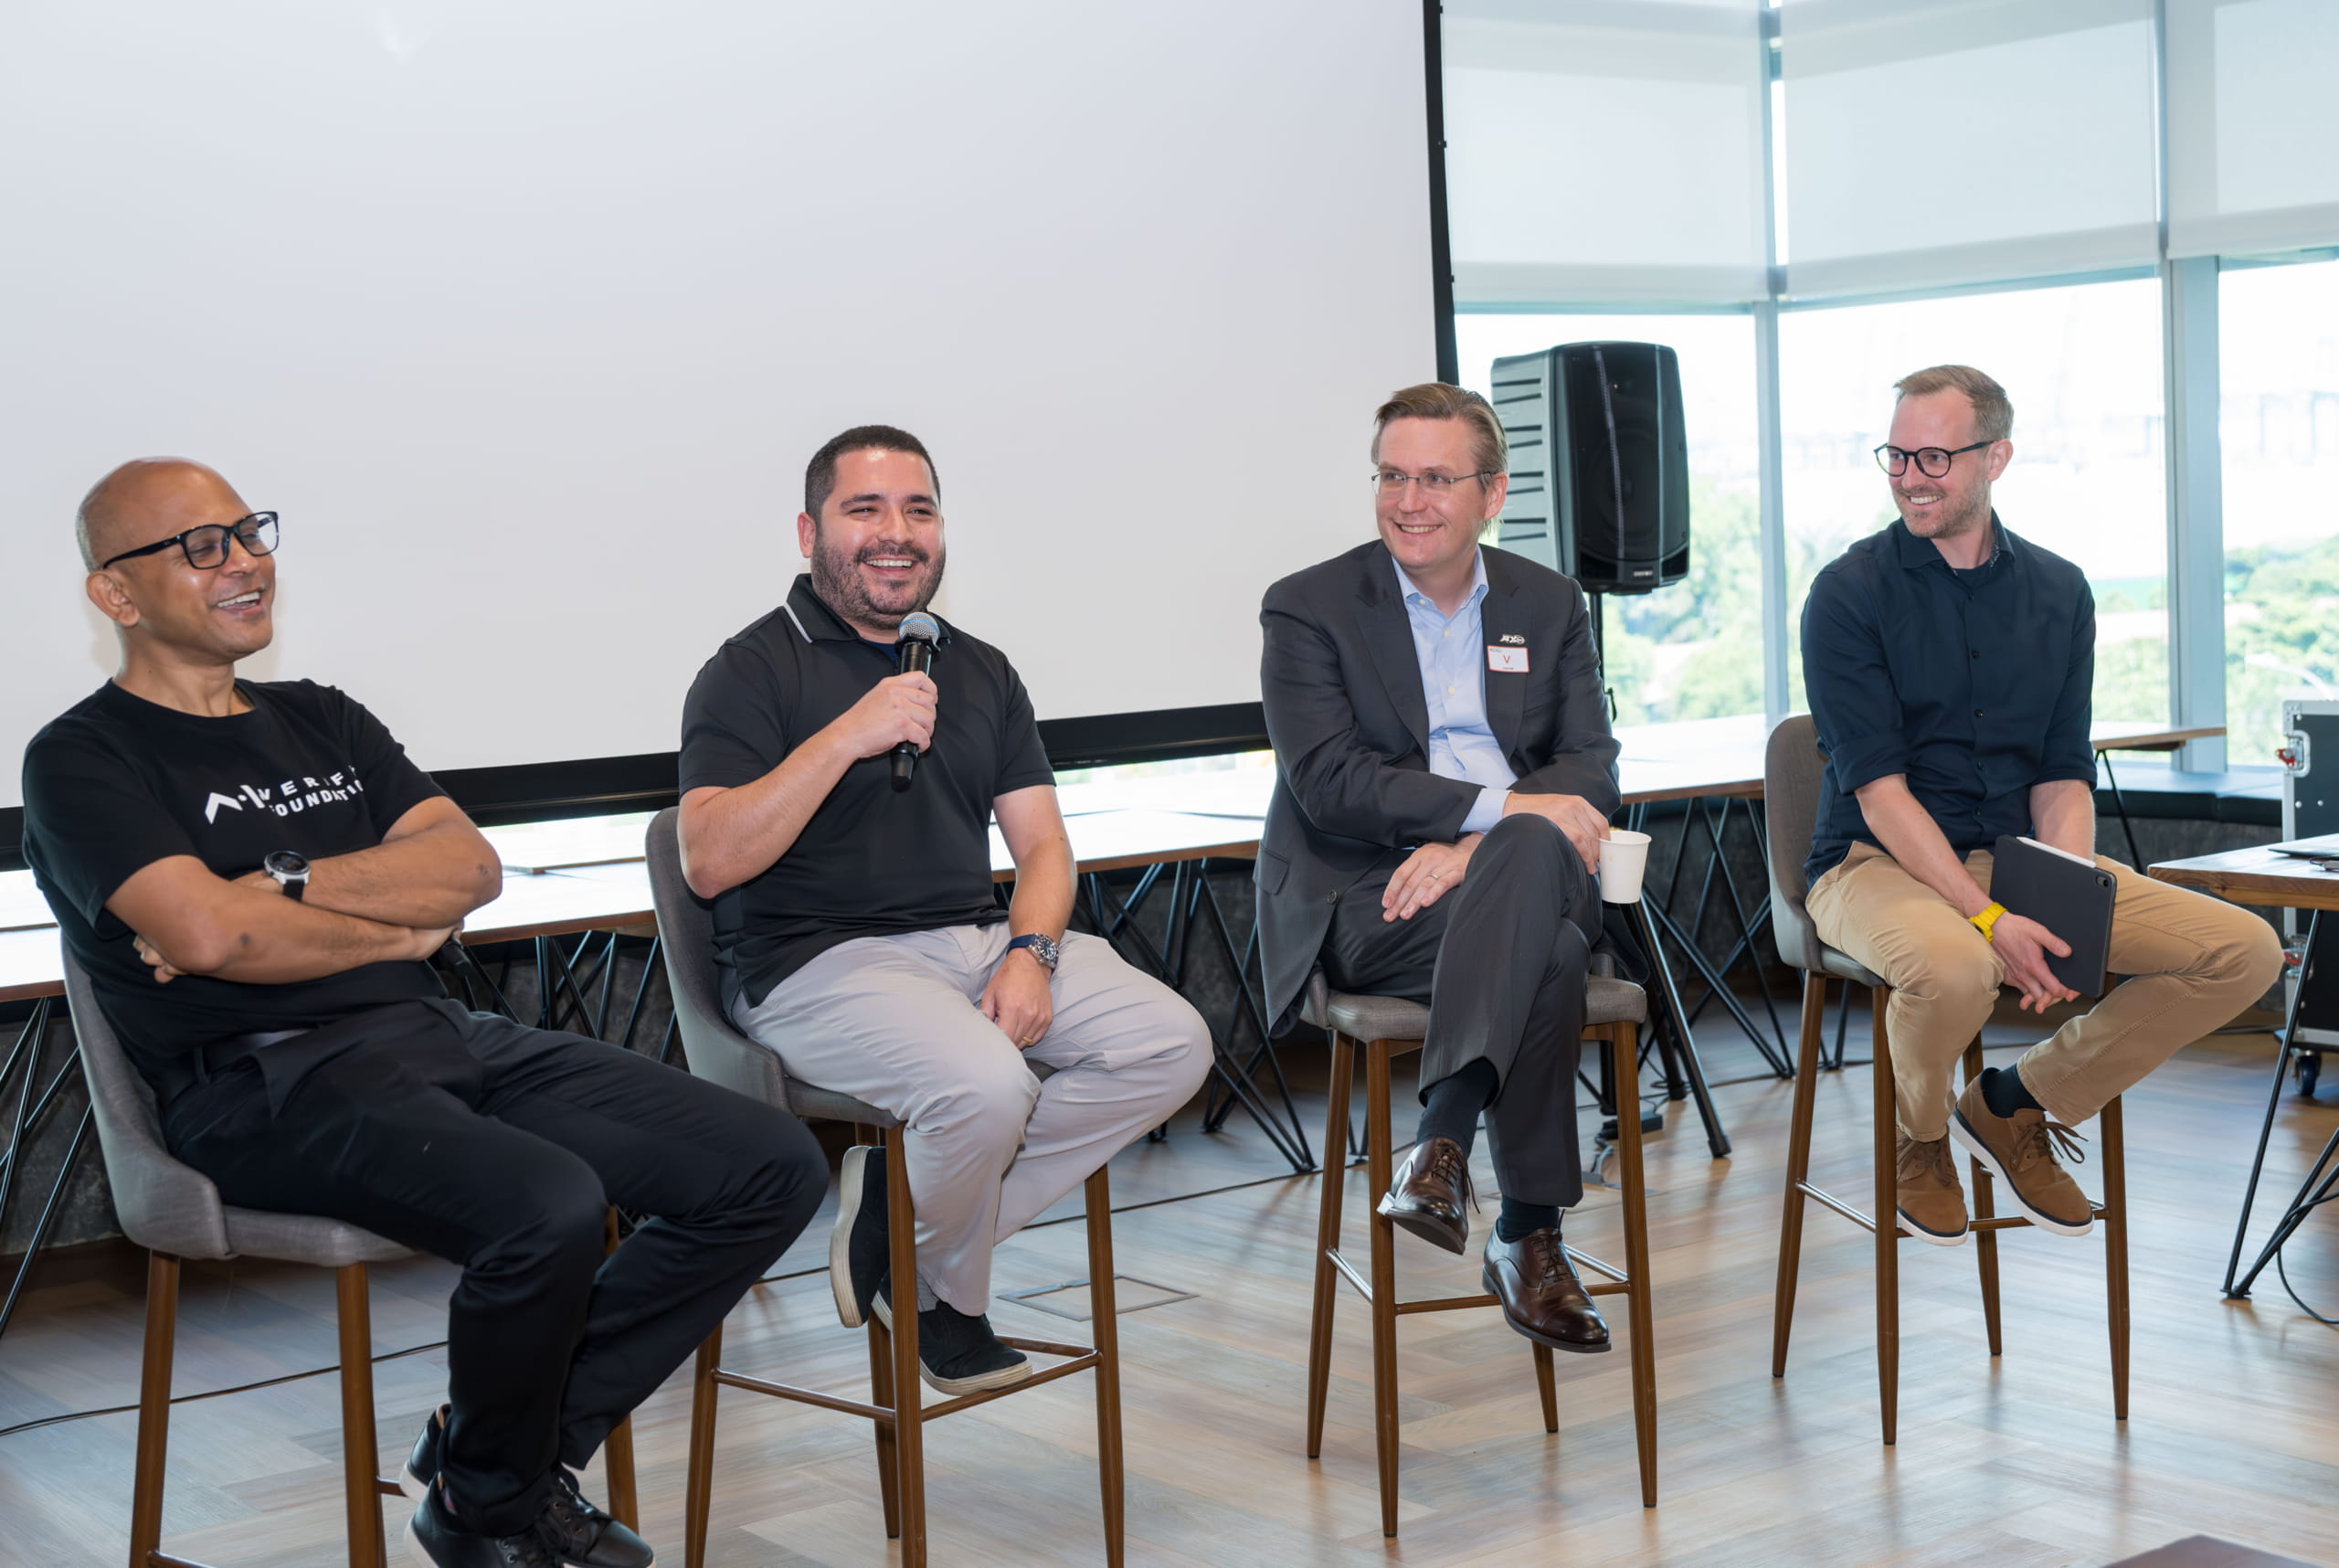
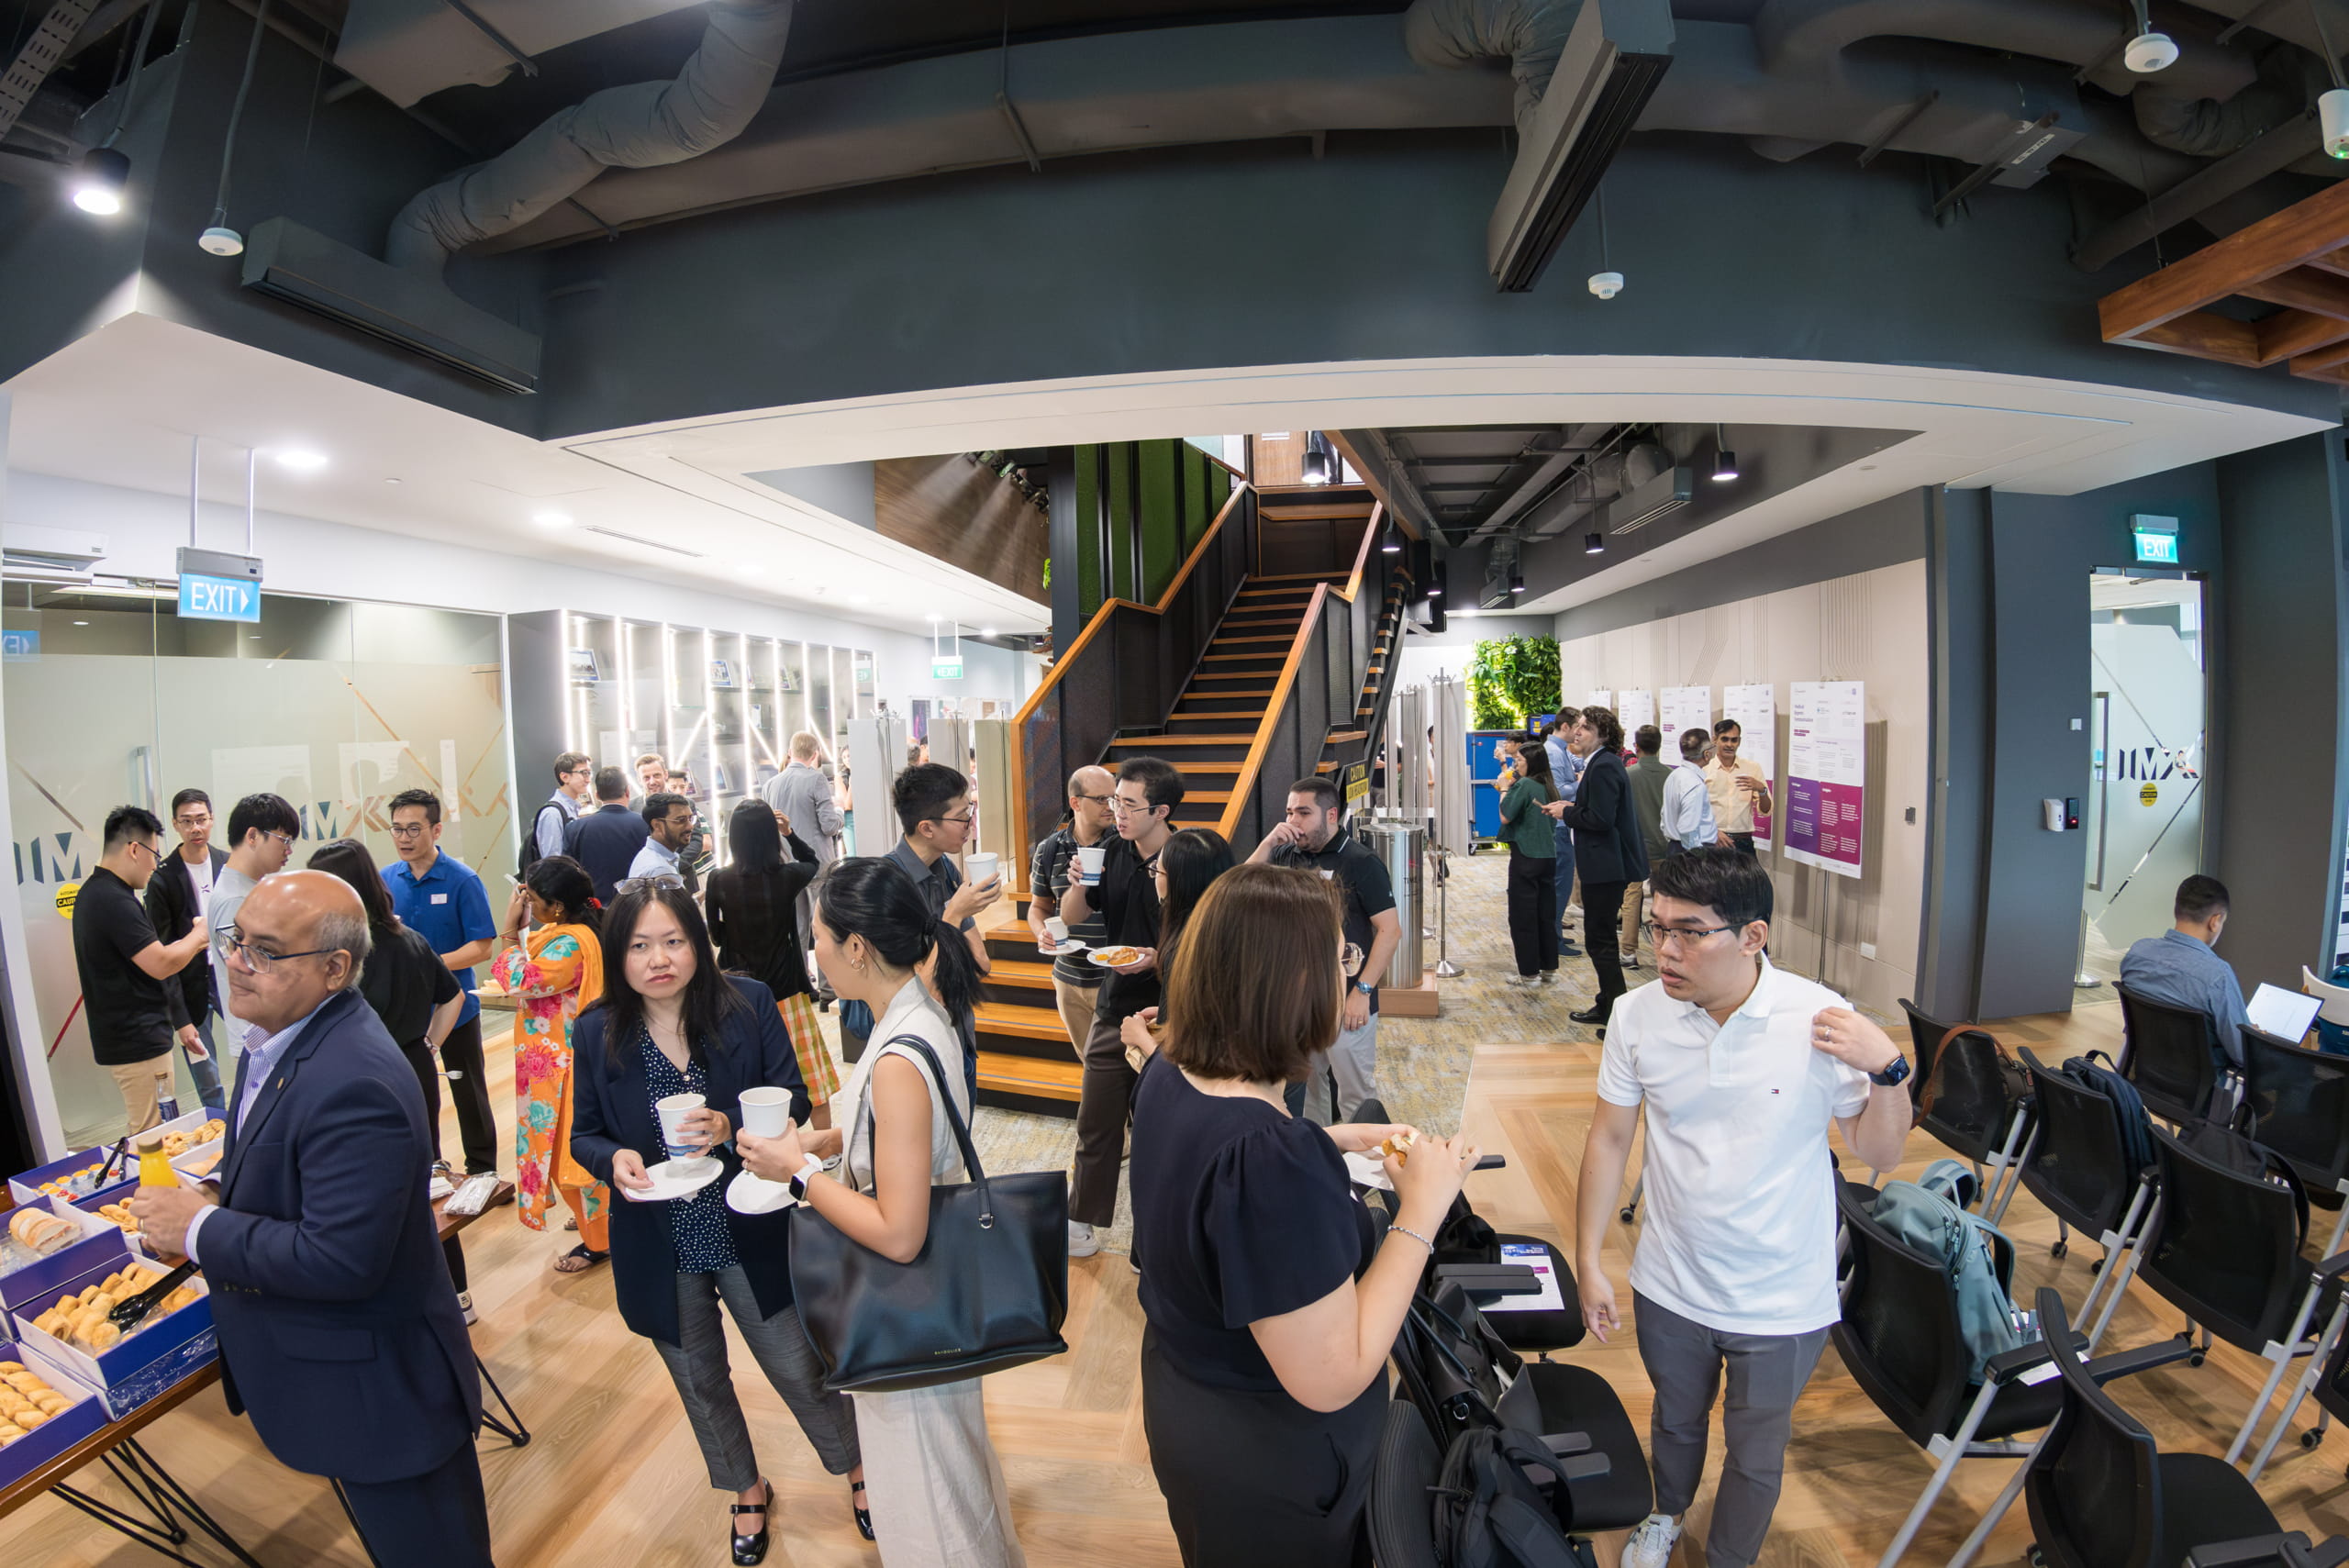
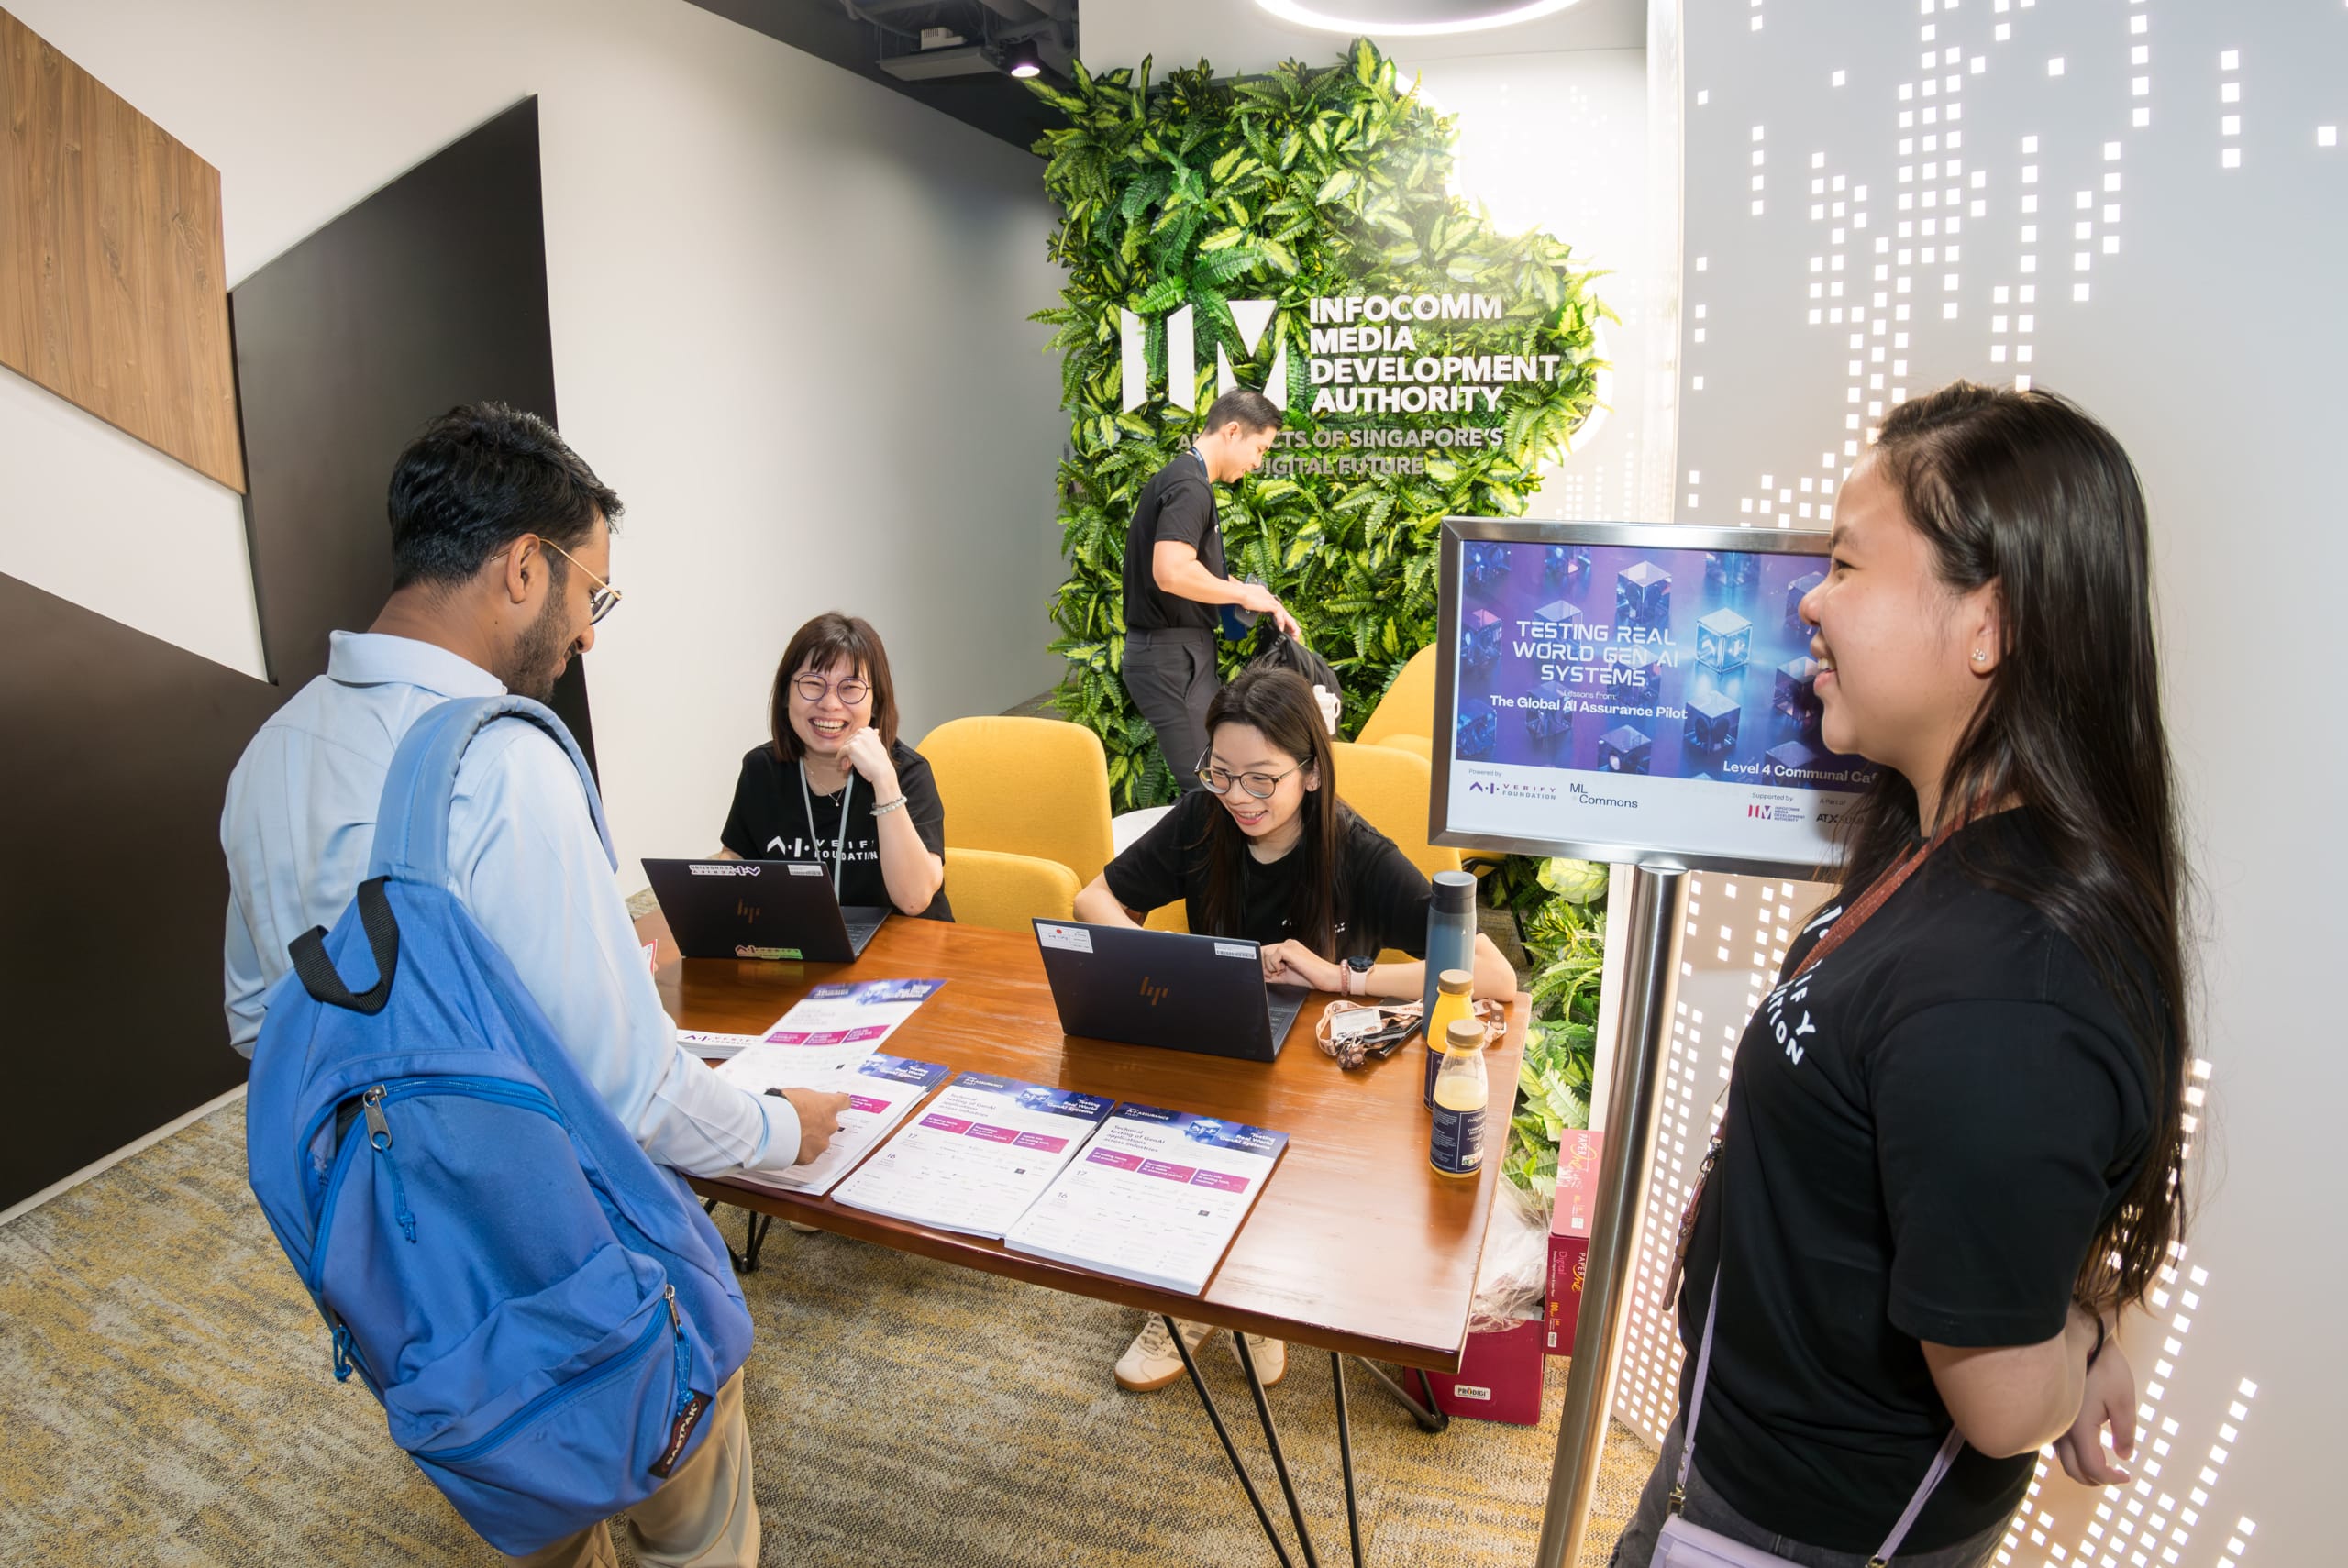
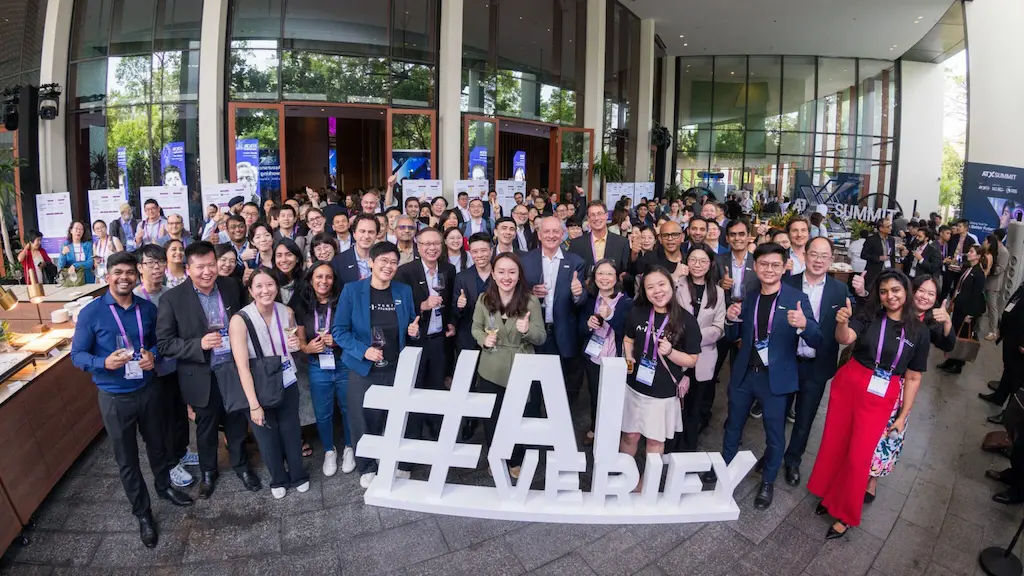
On May 30, we brought together almost 100 GenAI practitioners and ecosystem players together with our Global AI Assurance Pilot participants.
Making AI reliable, trustable – some might even say boring and predictable – for adoption at scale.
We spotlighted three major initiatives:
Insights and lessons from conducting the Global AI Assurance Pilot with interactive discussions.
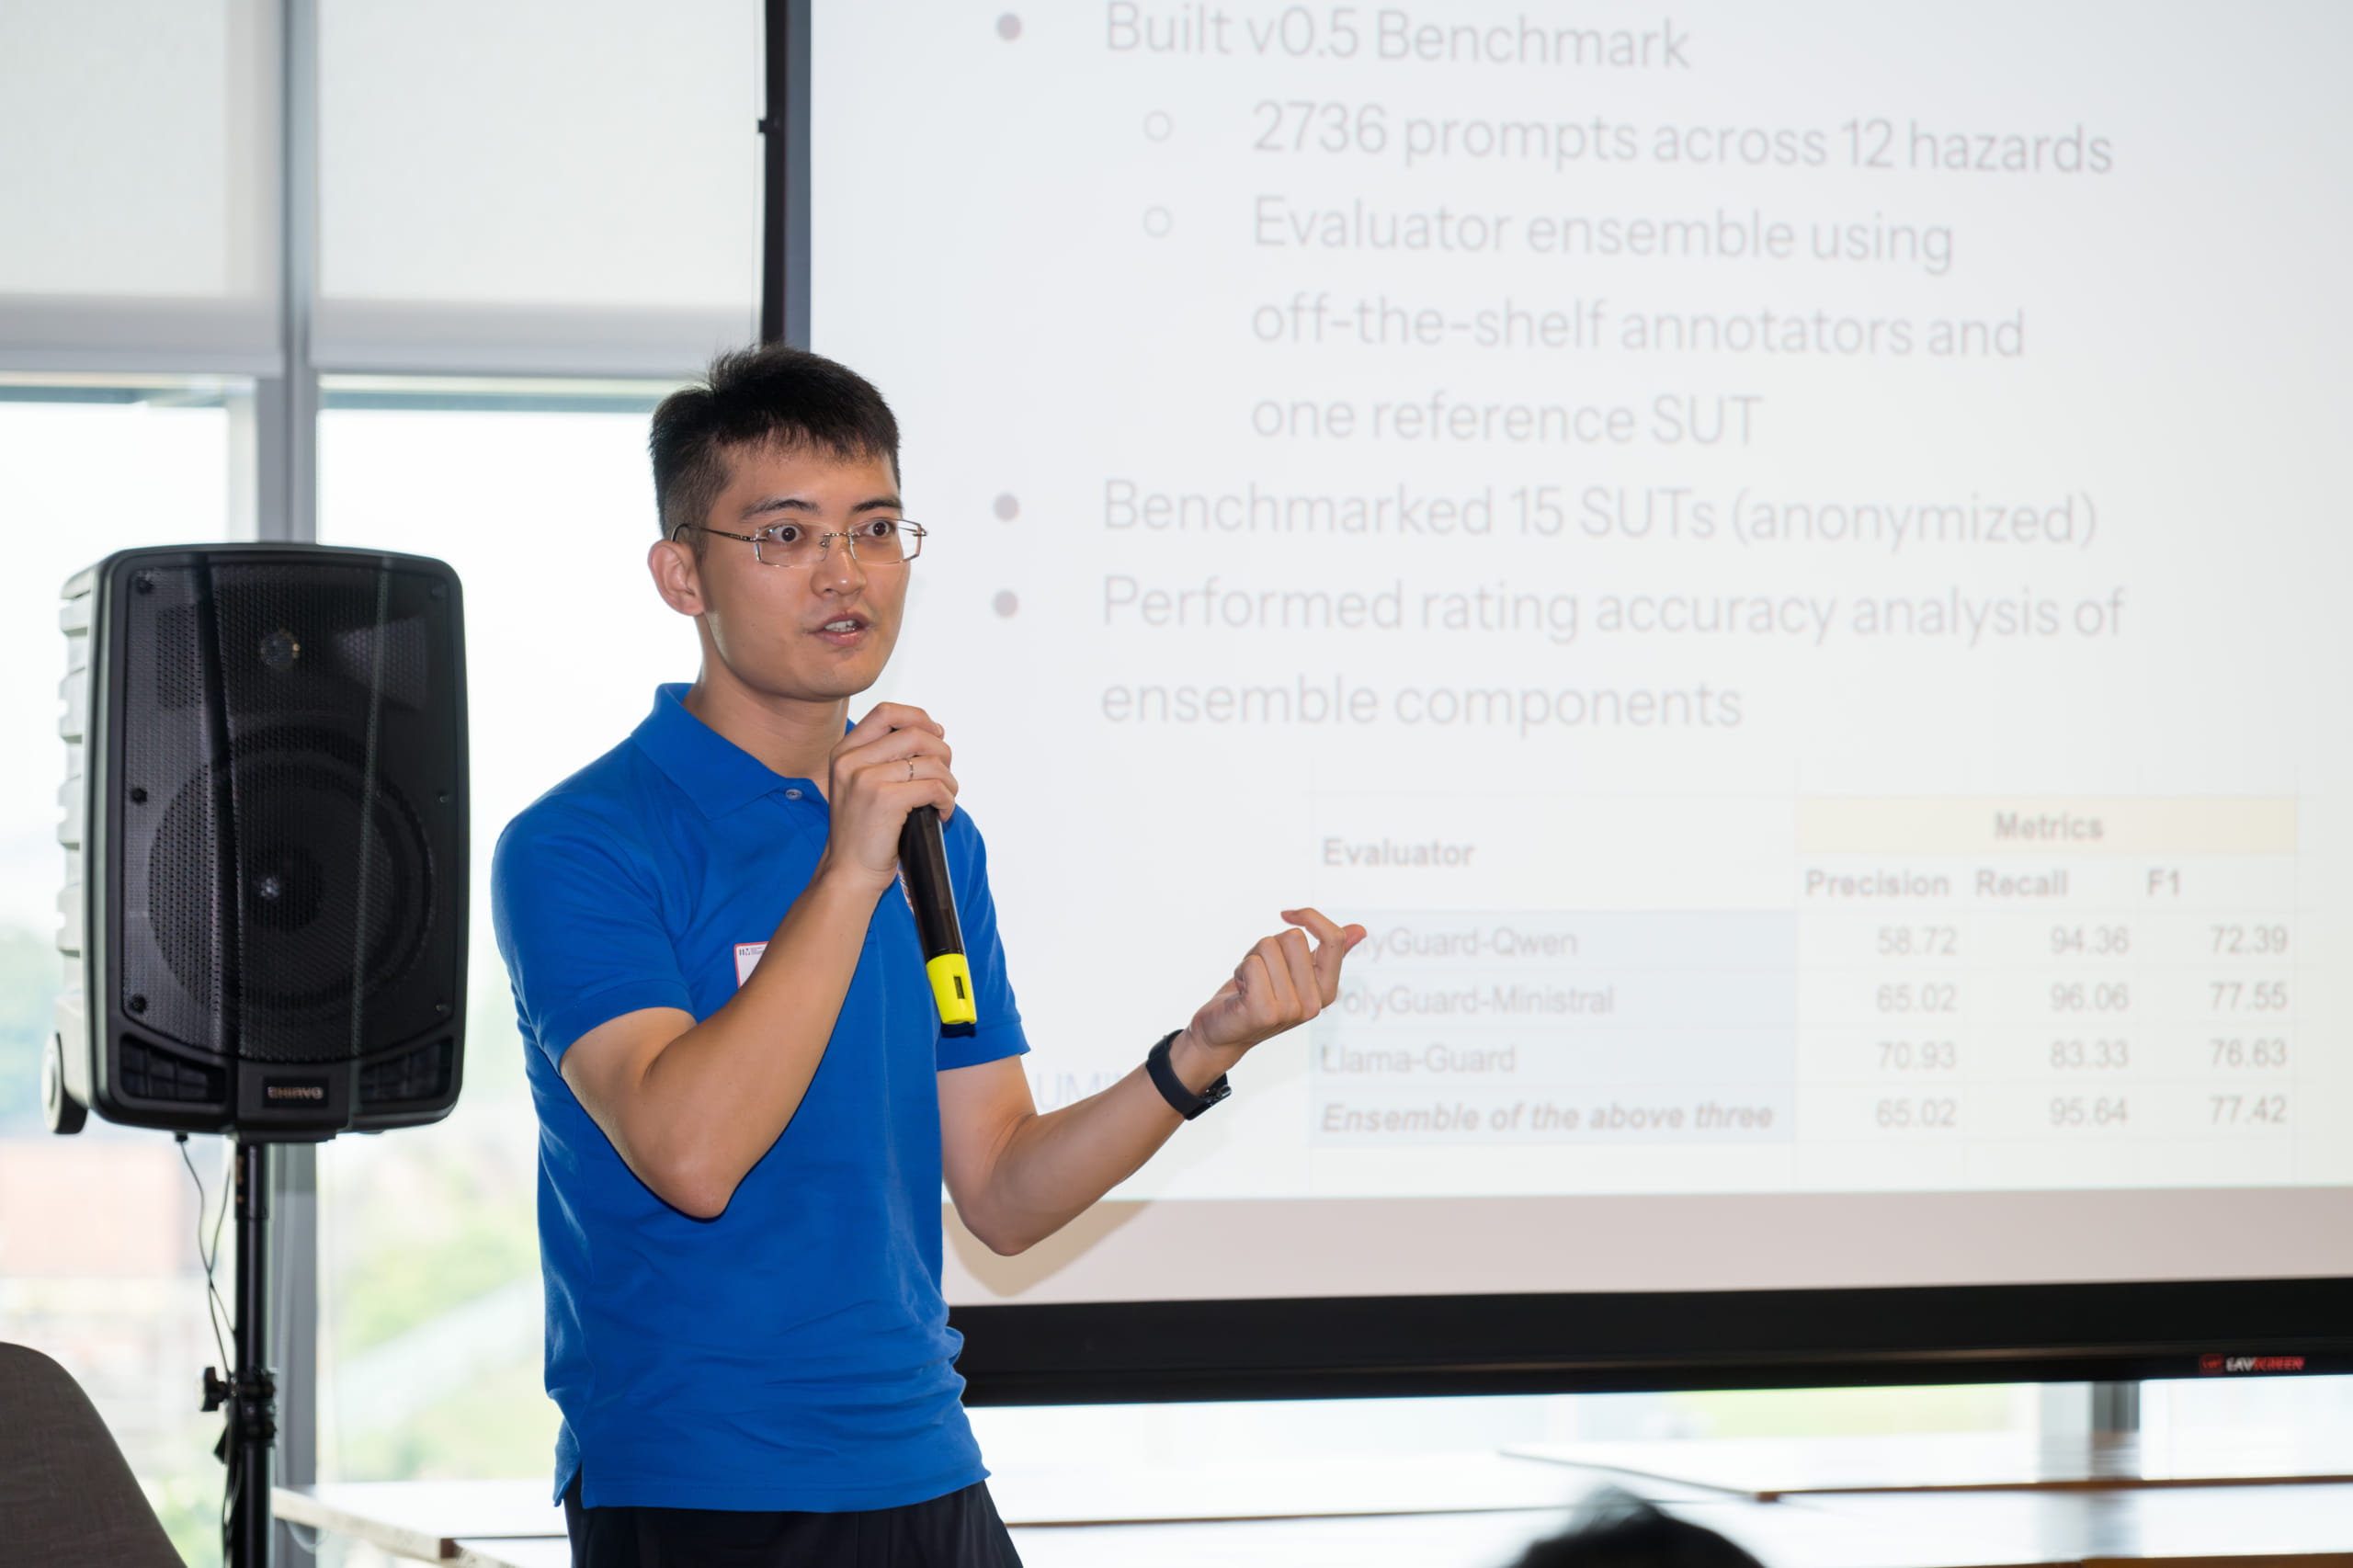
AILuminate Safety Benchmark for Chinese with our partners at MLCommons & NUS.
The Starter Kit by IMDA, a set of voluntary guidelines that coalesces emerging best practices and methodologies for the safety testing of LLM-based applications.
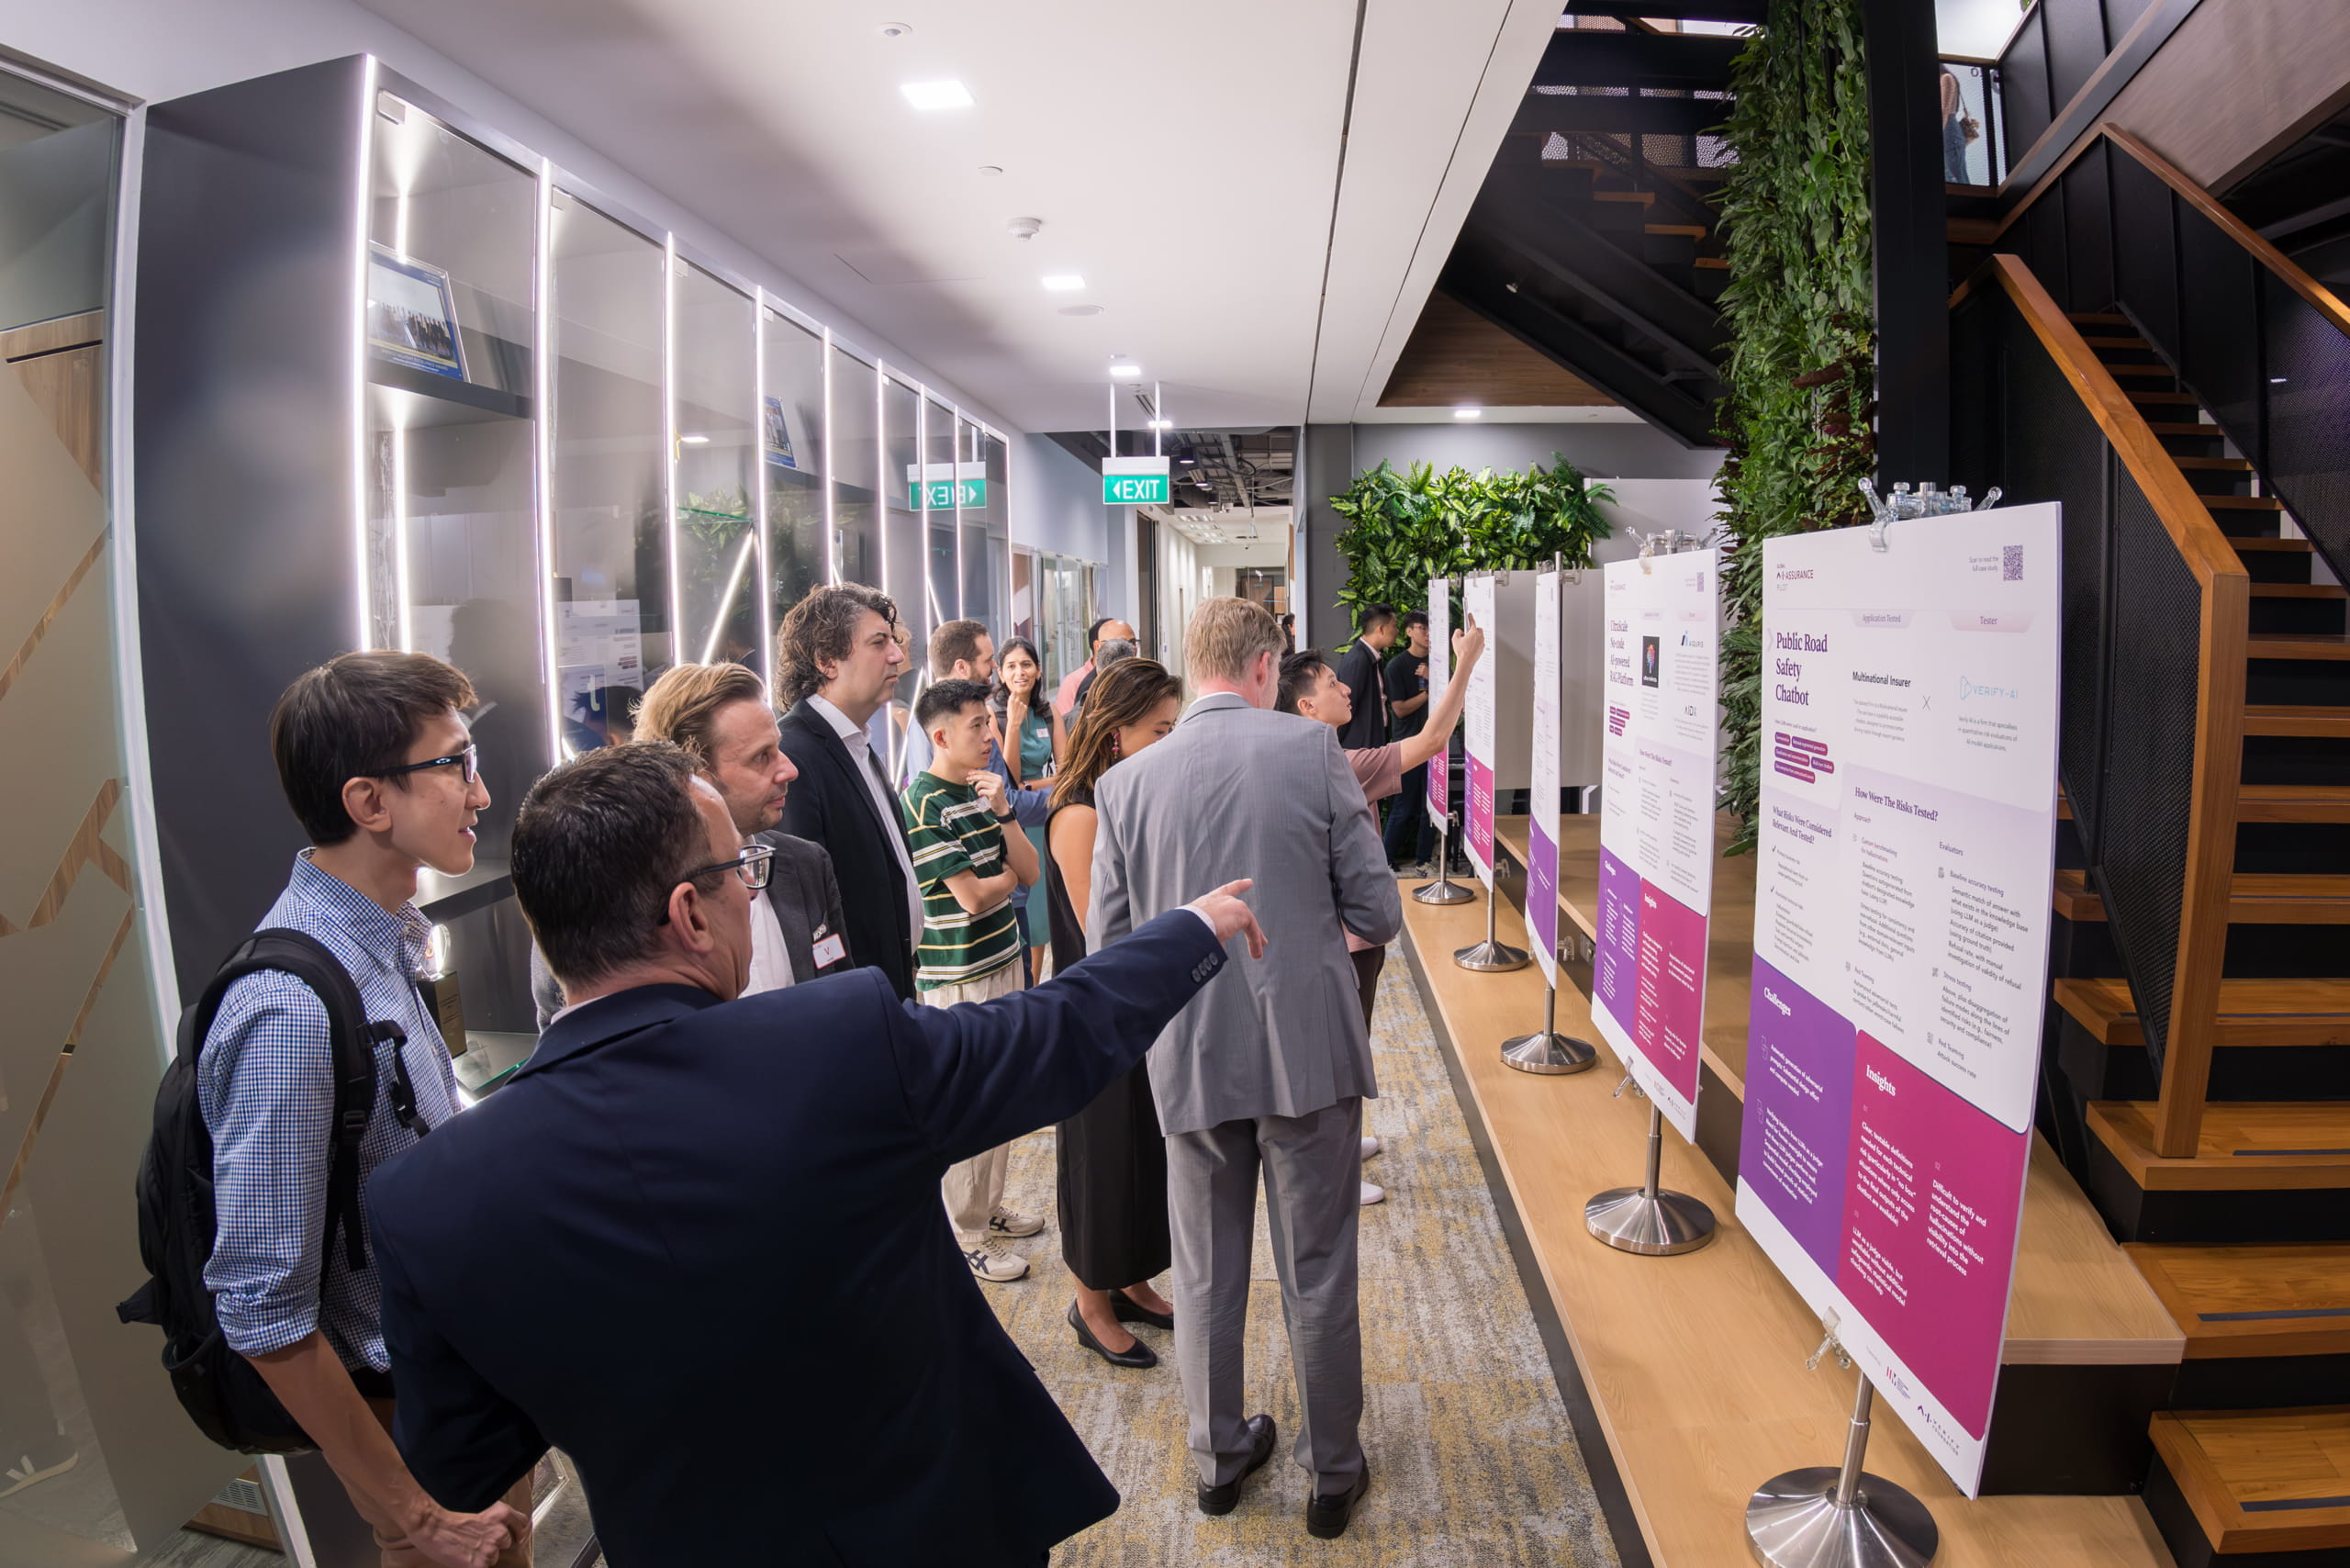
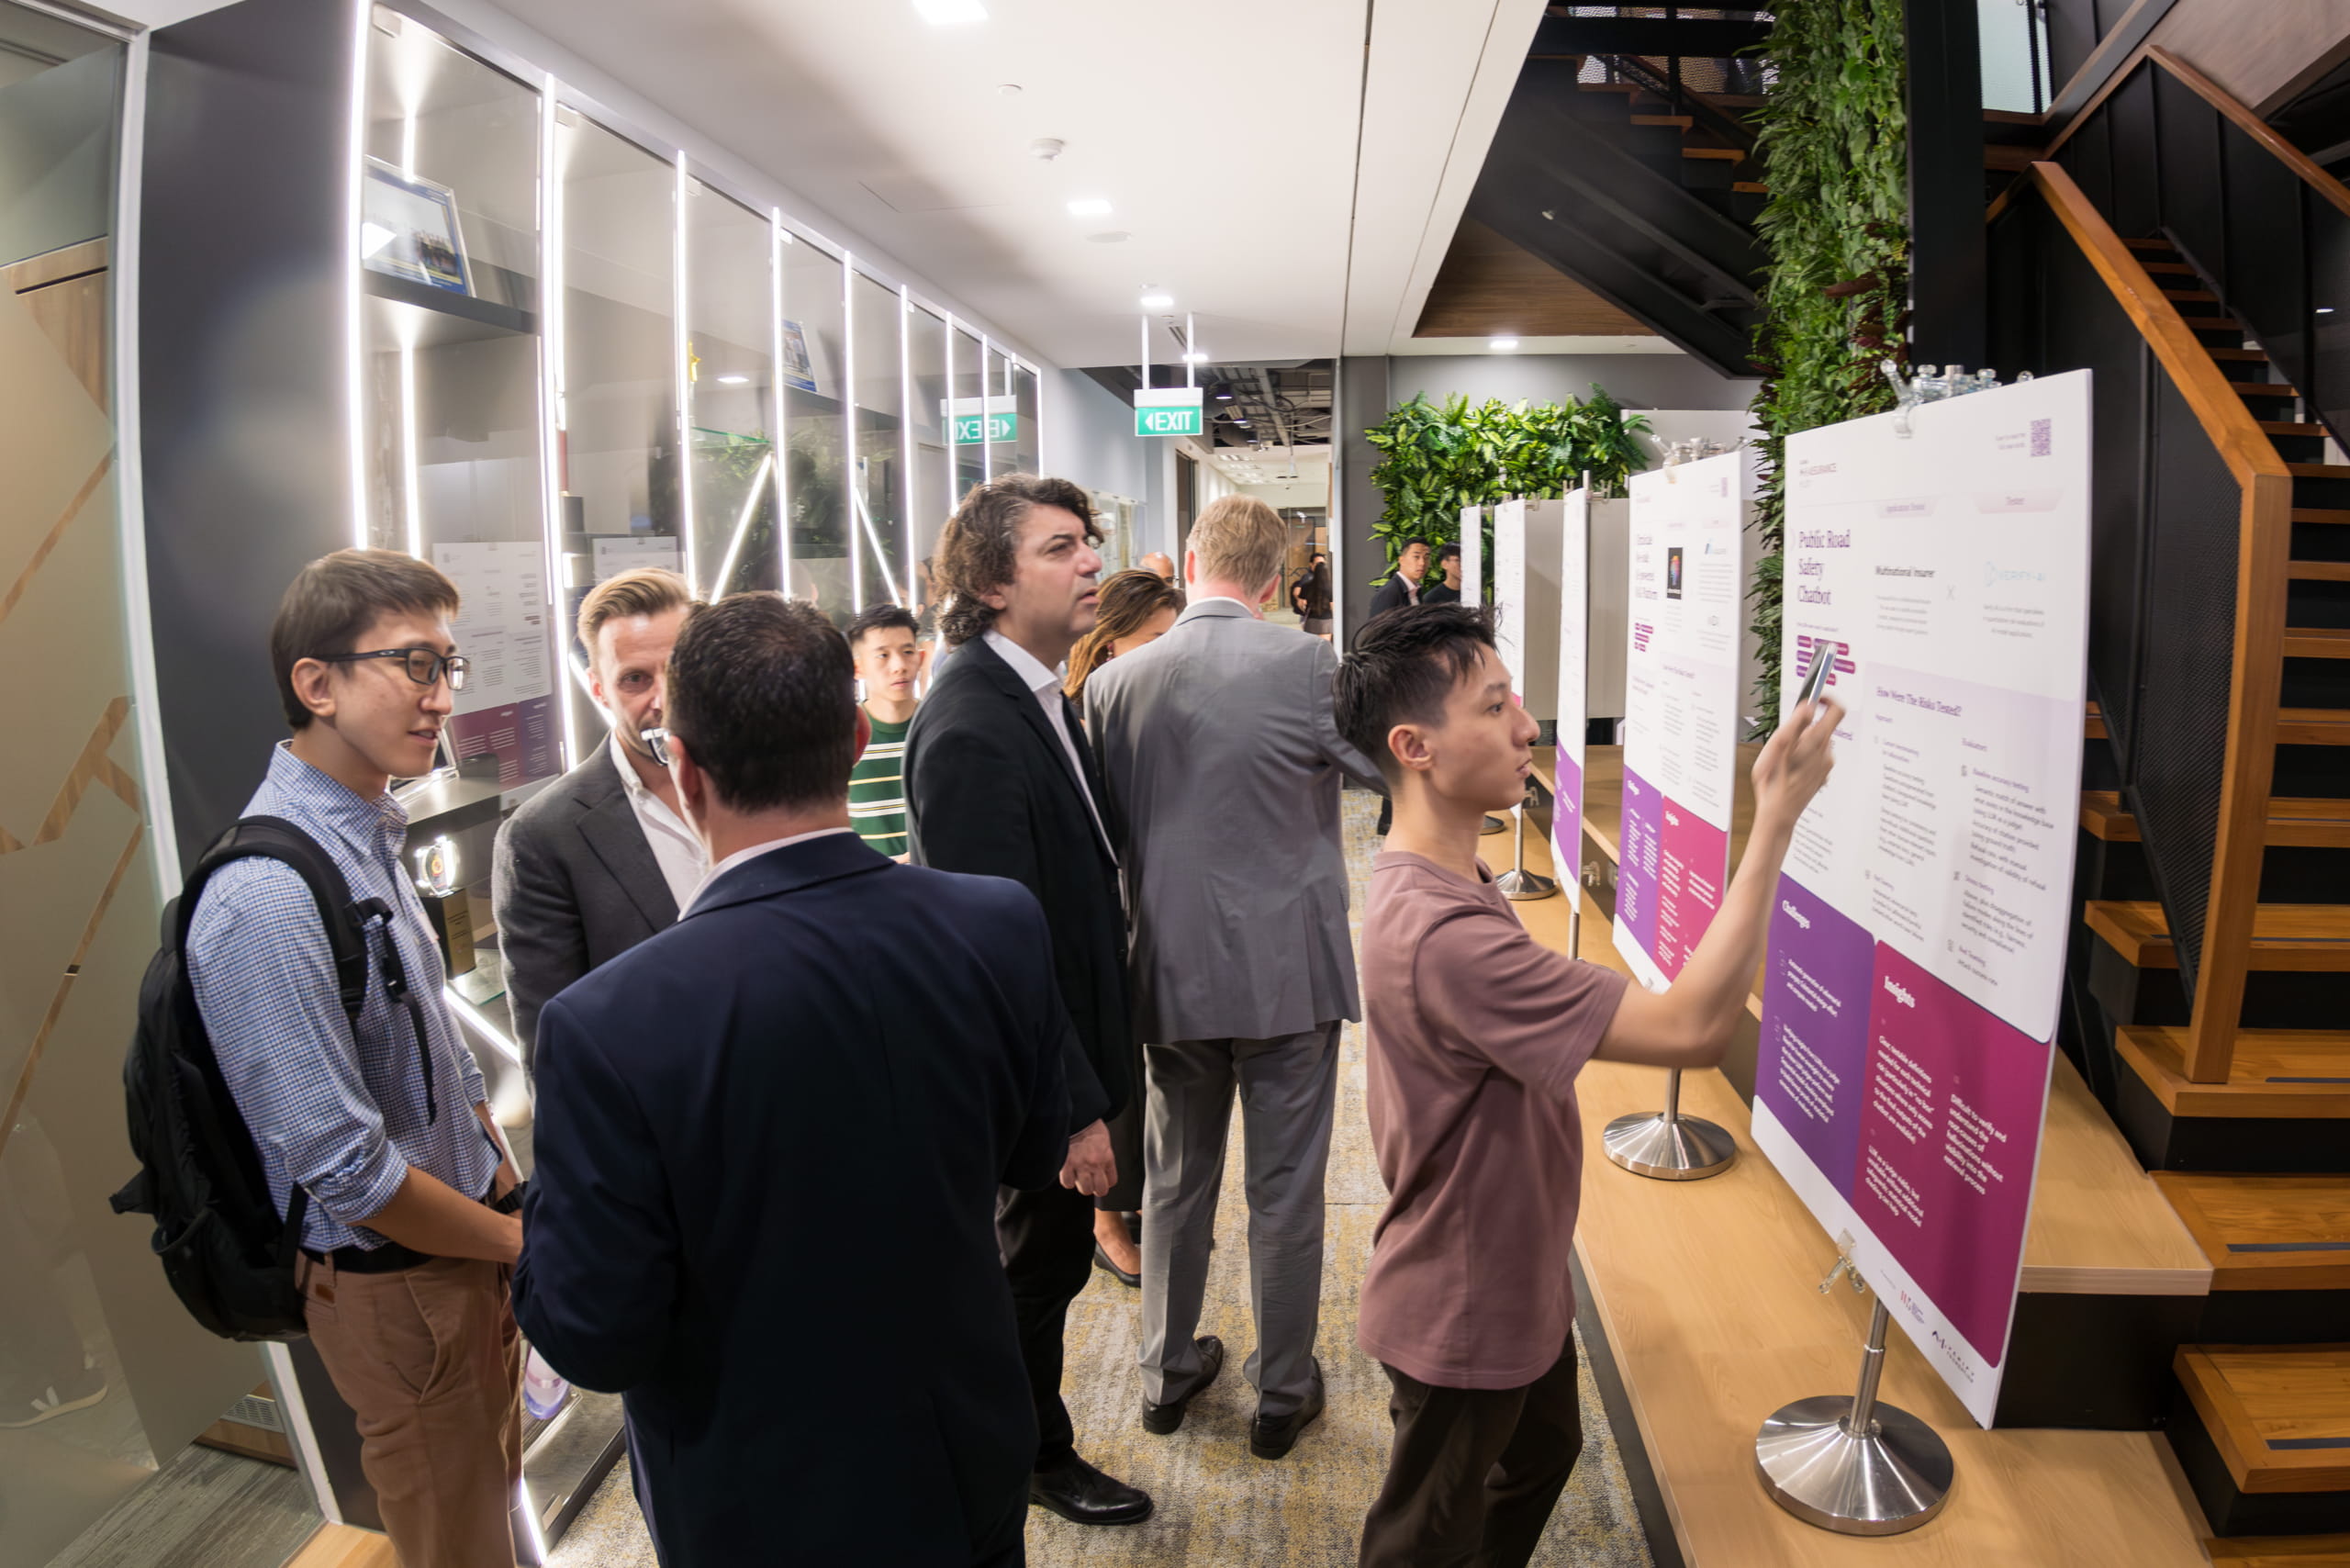
We showcased the case studies from the Pilot:
Read all case studies here.
Read the main report from Pilot here.
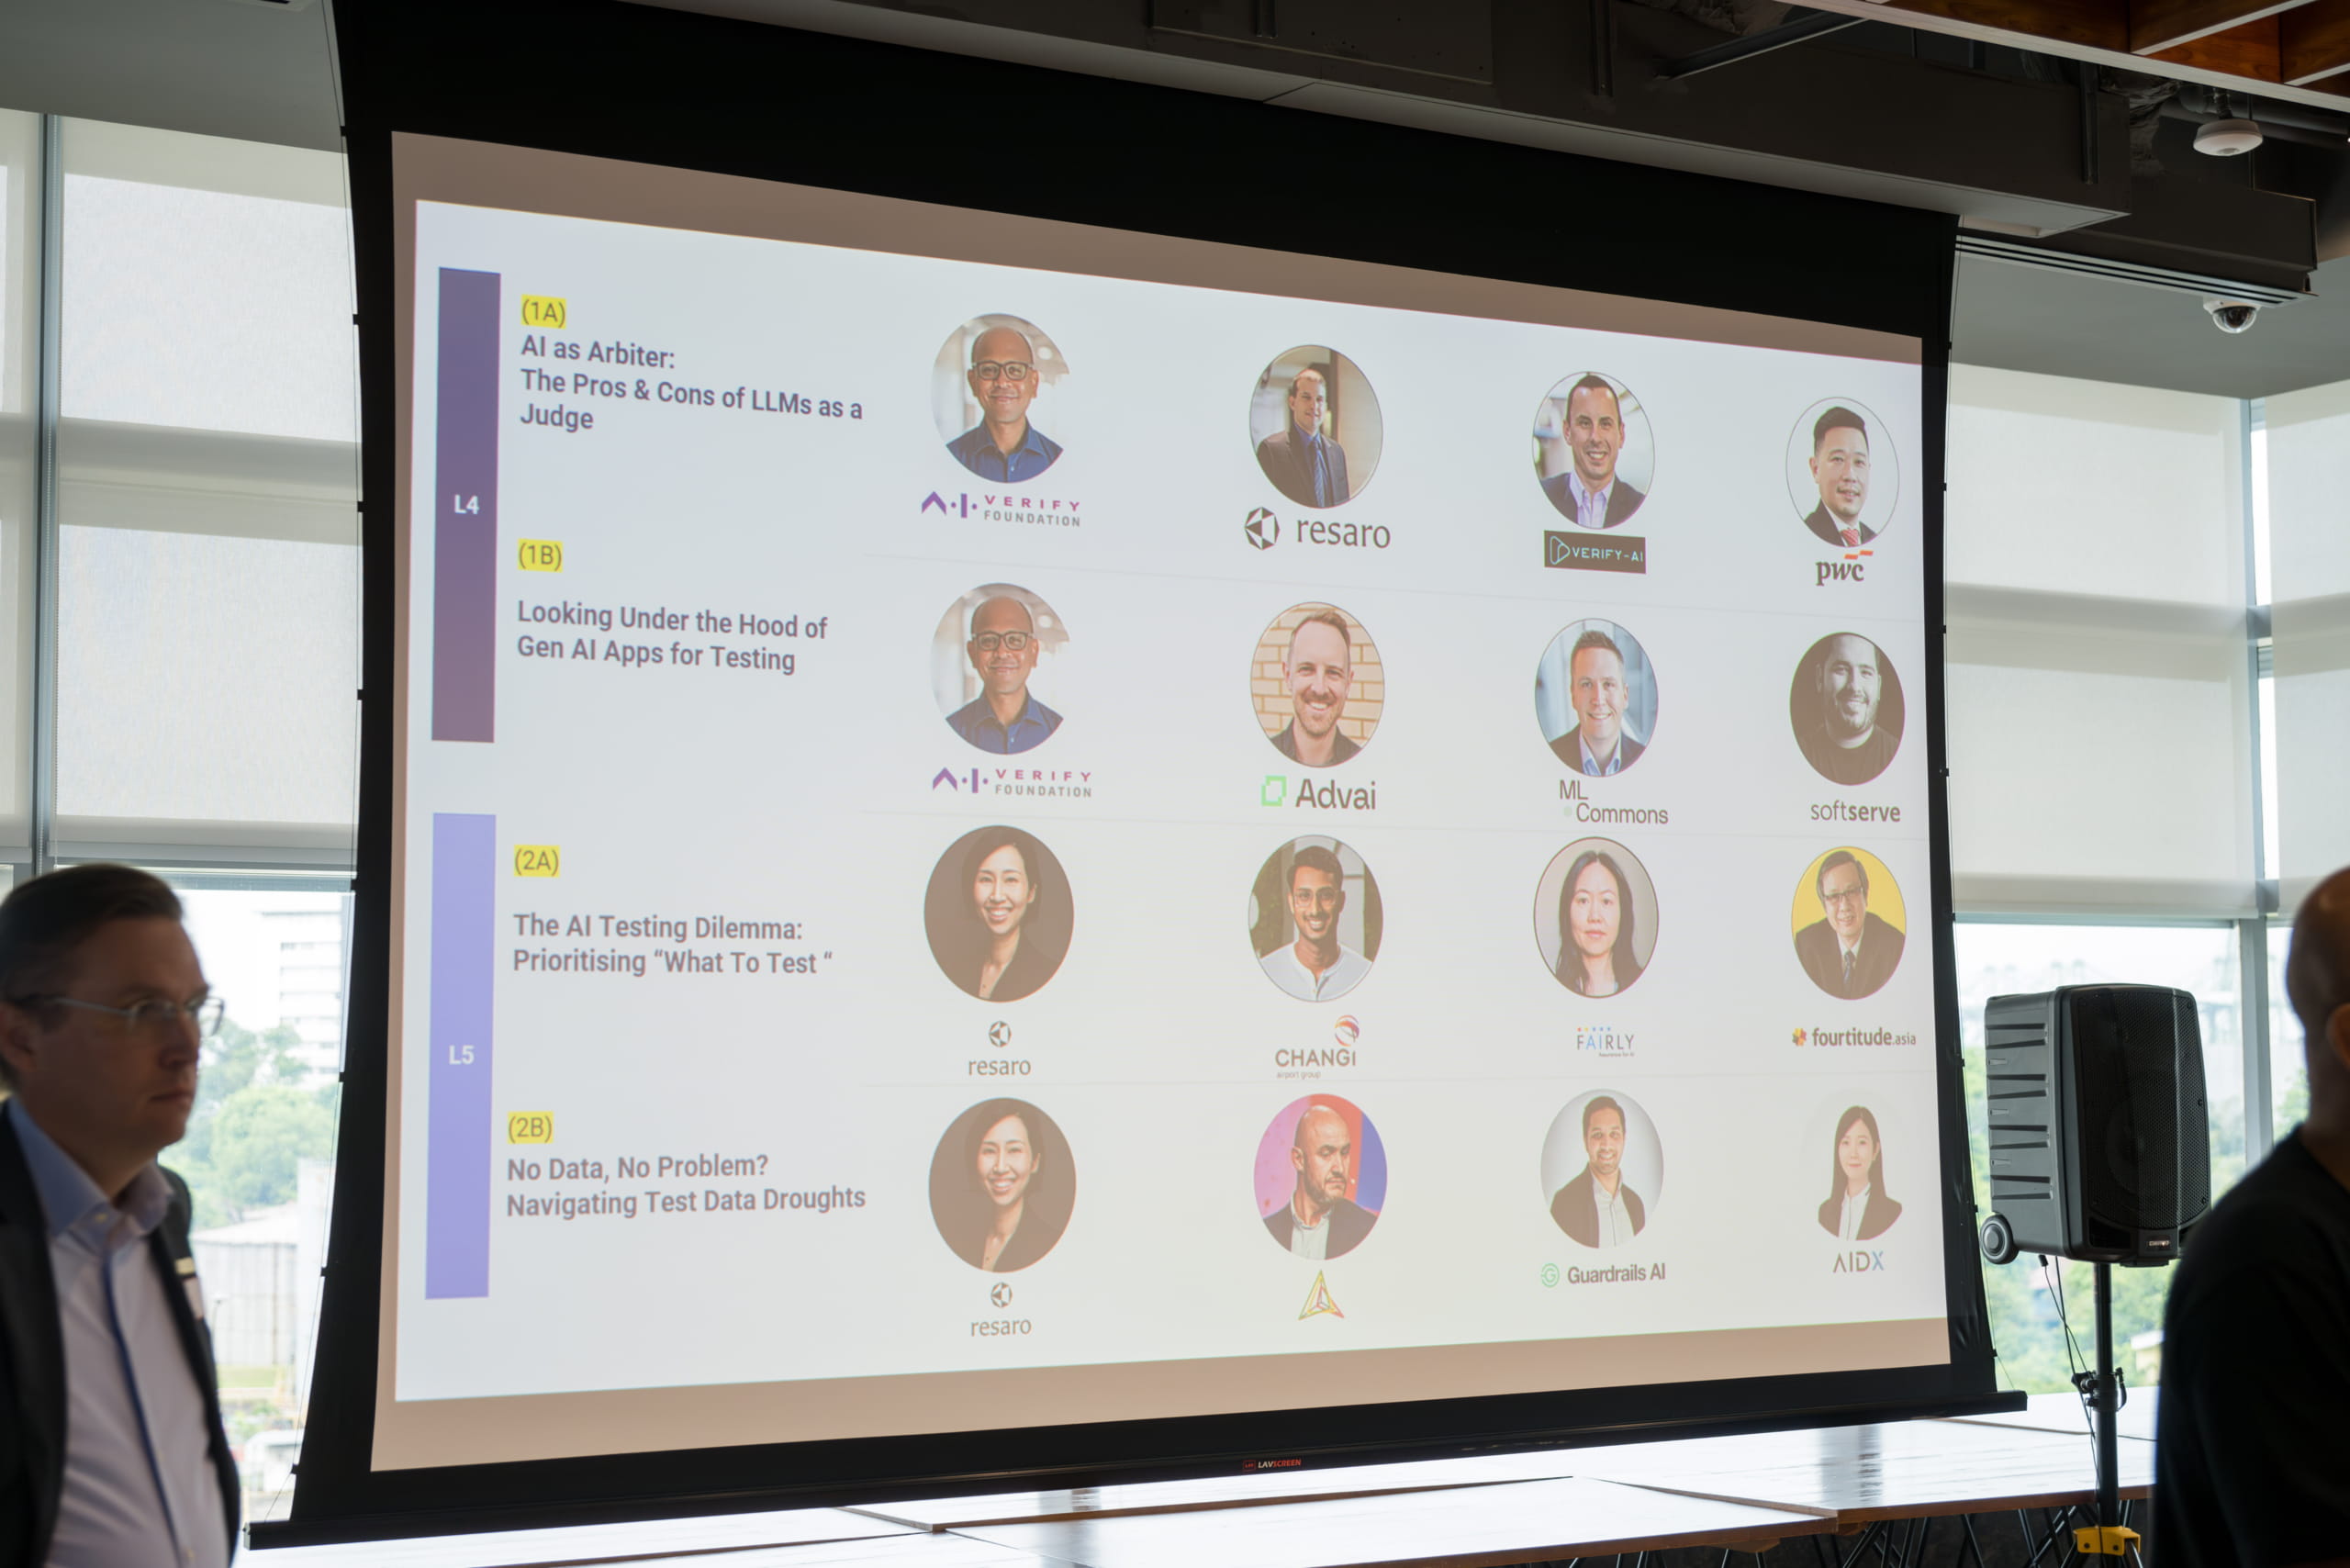
Here’s what we explored together during the interactive panel discussions:
This is how we build trusted AI, together — by testing the real-world, human-impacting cases, and sharing the processes and learnings with one another.